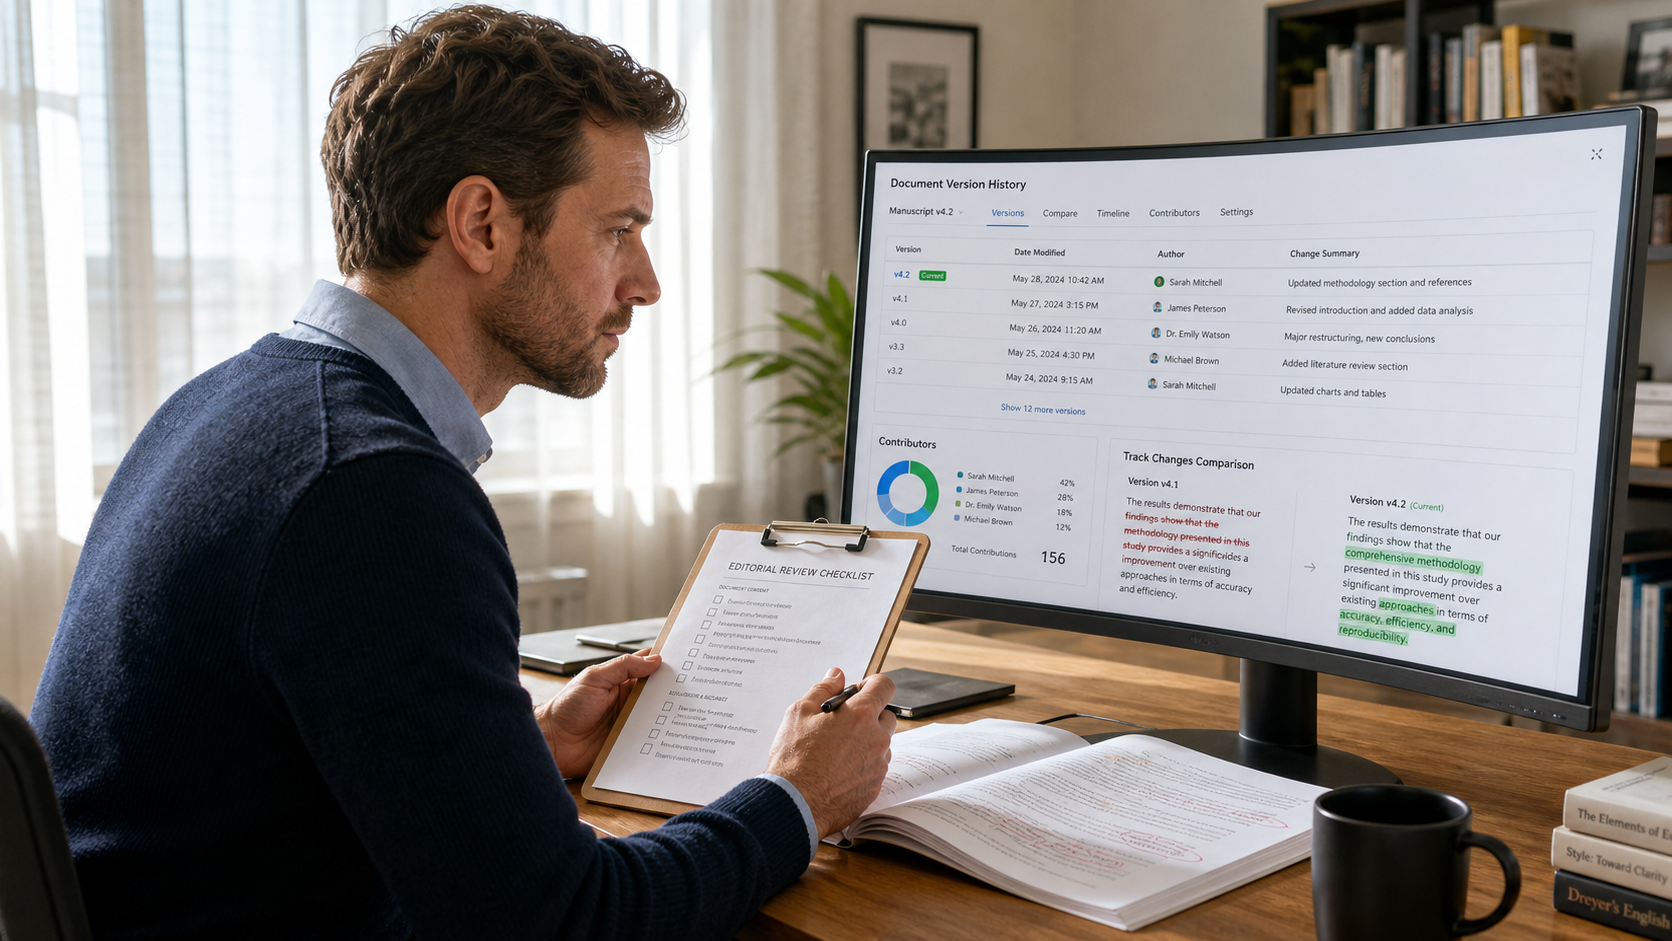

Teachers, editors, and hiring managers increasingly find themselves looking at a revision history or a typing pattern score without a clear sense of what to actually do with it. A single number rarely tells the whole story, and treating it as though it does leads to exactly the kind of overreaction or underreaction that makes this technology less useful than it should be.
A short, repeatable process solves this more reliably than intuition applied case by case, and it does not require becoming an expert in the underlying detection technology to use well.
Start with the Shape, Not Just the Score
Before looking at any automated score, look at the basic shape of the timeline itself. A genuine writing session typically spans more than one sitting, includes visible pauses of varying length, and shows small corrections scattered somewhat unevenly throughout rather than clustered in one uniform pattern.
A single uninterrupted session, however long, is not automatically suspicious on its own, some writers genuinely do finish work in one sitting. It is one data point worth noting, not a verdict to reach in isolation.
It also helps to compare the shape against the same person’s earlier work when that history is available. A writer who consistently produces long, uninterrupted sessions is showing a personal pattern, not a red flag. The same shape appearing for the first time, on a single high-stakes submission, is a different and more worthwhile thing to look at closely.
Check More Than One Signal Before Drawing a Conclusion
No individual signal, an AI detector score, a typing pattern score, or a plagiarism report, is reliable enough on its own to justify a serious conclusion. Each one can misfire independently, and each one measures a genuinely different aspect of a document.
Treating these signals as independent checks, rather than as one combined score, also protects against a subtler failure: a single tool that happens to bundle several checks into one number can hide exactly which underlying concern triggered the result, making it harder to ask the kind of specific question that actually resolves a case fairly.
A more reliable review typically checks:
- Whether an AI detector score is corroborated by anything else, rather than treated as sufficient by itself
- Whether a typing pattern or revision history score lines up with what the writer’s other submitted work typically looks like
- Whether a plagiarism report flags actual unattributed matches, not just stylistic similarity to other sources
- Whether the writing quality and depth match what would be expected from this specific person at this specific stage
Ask Before You Accuse
Every credible detection tool in this space describes its own output as a supporting signal, not a final verdict, a description worth taking seriously rather than treating as a disclaimer to skip past. A short, specific, low-stakes question resolves the overwhelming majority of unusual results far faster and more fairly than an immediate formal accusation.
The most useful version of this question is narrow and concrete: asking someone to walk through one specific paragraph, explain a particular research choice, or describe where a specific idea came from. A broad, open-ended accusation invites defensiveness. A specific, narrow question invites an actual answer.
Keeping a written record of that conversation matters too, for both sides. If the explanation resolves the concern, a brief note closes the loop cleanly. If it does not, that same record becomes the actual basis for any further step, rather than a vague recollection of an informal chat weeks or months later.
Weigh the Stakes Before Escalating
A low-stakes assignment does not need the same level of scrutiny as a thesis defense, a final hiring decision, or a piece heading to publication under a byline. Matching the depth of review to what is actually riding on the outcome keeps the process proportionate, rather than treating every flagged document with the same maximum level of suspicion regardless of what is actually at stake.
For genuinely high-stakes decisions, a brief live conversation, a short oral defense of a specific claim, or a request to see earlier drafts remains harder to fake convincingly than any single automated score, and it tends to resolve the underlying question directly instead of inferring an answer from metadata.
A useful rule of thumb is to ask what actually happens if the review is wrong in either direction. A low-stakes assignment reviewed too leniently costs very little. A high-stakes hiring decision or publication reviewed too leniently, or too harshly, carries real consequences on both sides, which is exactly the kind of case that deserves the deeper version of this process rather than a quick glance at a single score.
It also helps to know what legitimate assistance actually looks like in a revision history. A pass through a style tool such as the AI Humanizer, done inside the document itself, shows up as ordinary editing, not as the kind of single, unexplained insertion that a fabricated typing session is built to disguise.
The Checklist Is a Starting Point, Not a Formula
None of this reduces to a fixed formula that produces a clean answer every time. It is a discipline: look at more than one signal, ask a specific question before drawing a conclusion, and match the level of scrutiny to what is actually at stake. That discipline holds up regardless of which detection tools exist this year or which ones a workaround eventually catches up to.
The reviewers who get the most value out of this technology tend to be the ones who treat the checklist as a habit rather than a one-time policy decision, revisiting it periodically as the tools themselves change, rather than setting a process once and assuming it will keep working exactly as designed indefinitely.
For more on how AI detection and writing verification tools work in practice, further reading on the Phrasly blog covers the underlying research for teachers, editors, and hiring teams applying this kind of review.